Key takeaways
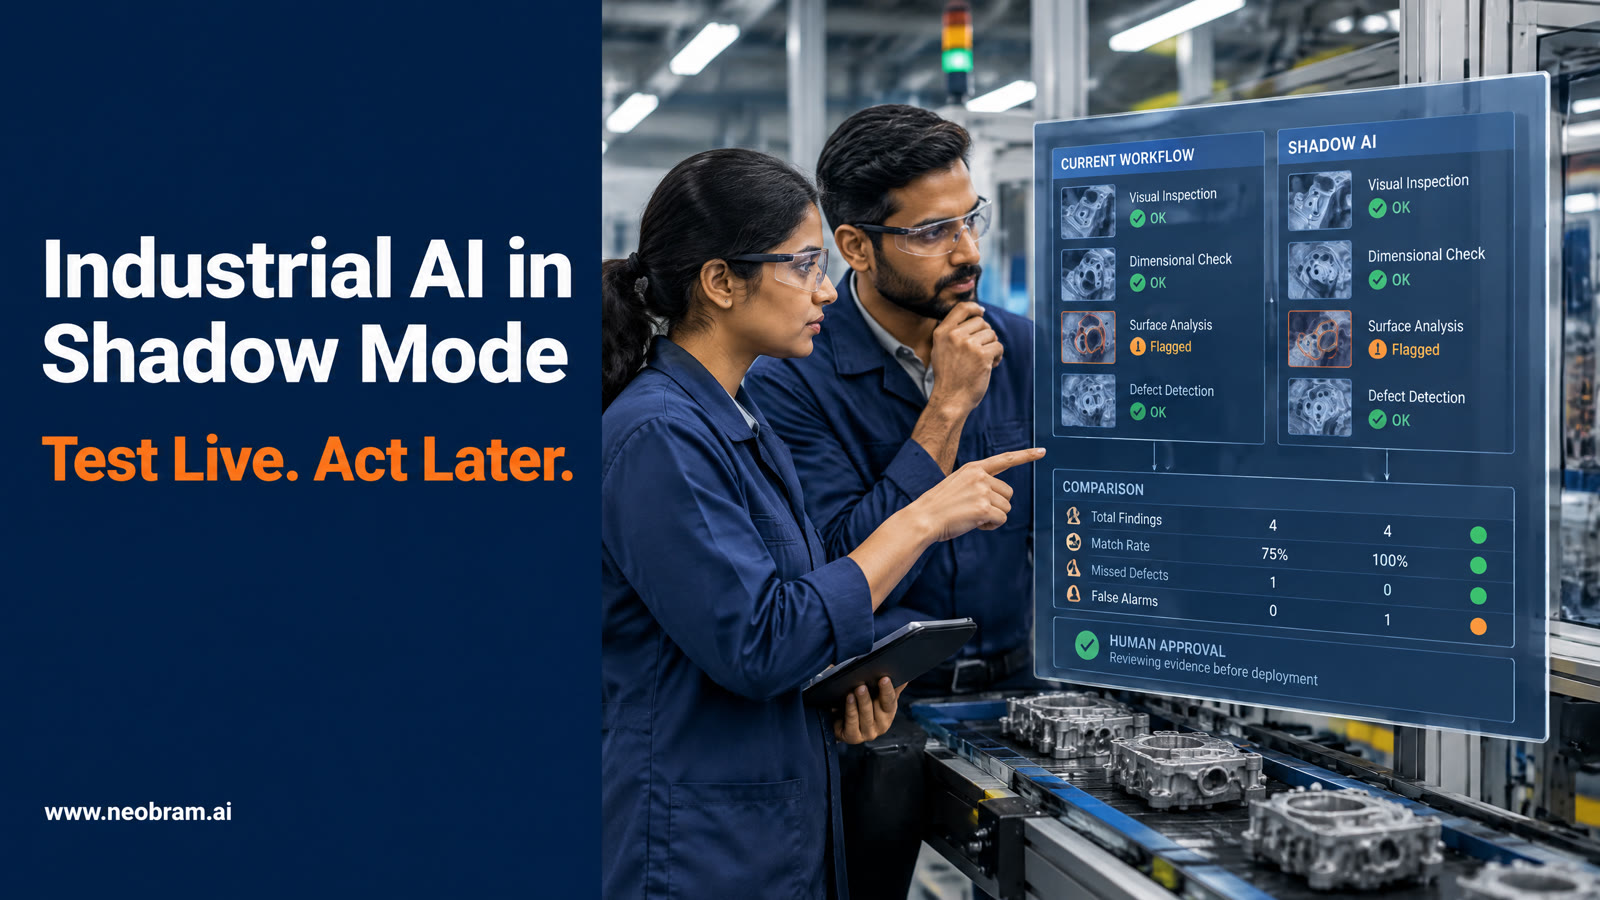
- Shadow mode means the candidate system receives representative live inputs and records what it would recommend while the existing authorized workflow remains in control.
- A read-only label is not enough: deny write credentials, isolate the shadow path from control interfaces and verify that no output can change production state.
- Compare the AI with the evidence available at decision time and with the later operational outcome; a human action alone is not automatically ground truth.
- Acceptance criteria should cover operating-envelope coverage, decision quality, abstention, latency, workflow burden, traceability and safe failure—not one aggregate accuracy score.
- Promotion should expand one permission at a time, with named owners, rollback conditions and post-release monitoring already defined.
A safe parallel run is more useful than another polished demo
A model can look convincing in a workshop and still fail when it meets live production. Sensor timestamps drift. Product mix changes. Operators use local rules that were never written down. Confirmed outcomes arrive hours, days or maintenance cycles after the original recommendation. The integration may also behave differently under real queue depth, network delay and access controls.
Shadow mode is a disciplined way to expose those conditions without giving the candidate system operational authority. The AI observes the same events as the authorized workflow and records what it would have recommended, but its output cannot change a machine, quality record, work order, schedule or customer-facing action.
NIST's AI Risk Management Framework Playbook says performance or assurance criteria should be demonstrated under conditions similar to deployment, with limitations beyond those conditions documented. It also calls for domain experts and users to inform assessments, and for systems to fail safely when they operate beyond their knowledge limits. [1] Shadow mode creates a practical bridge between controlled evaluation and those deployment-like conditions.
Shadow mode is not a quiet production launch. It is a live evidence phase in which the current authorized process remains the only path that can act.
What industrial AI shadow mode means
An industrial shadow deployment has three defining properties. It uses representative live inputs. It produces a complete candidate result on the timing expected in production. It has no authority to alter the operational workflow.
The same pattern appears in commercial machine-learning infrastructure. AWS describes shadow testing as routing a copy of live inference requests to a new variant while only the production variant's response reaches the application. The shadow response can be logged for offline comparison. [4] Microsoft describes an equivalent enterprise-agent pattern in which the system runs on live cases but does not update records, contact customers, change status or interrupt the existing workflow. [6]
For industrial use, the separation must cover physical and digital actions. A shadow quality model may classify an image, but it cannot reject a part or place a lot on hold. A shadow maintenance agent may draft a recommendation, but it cannot create, approve or close a work order. A shadow production optimizer may calculate a schedule, but it cannot publish it to the manufacturing execution system.
| Mode | Inputs | Output visibility | Operational authority | Best use |
|---|---|---|---|---|
| Offline replay | Historical snapshots | Evaluation team | None | Regression testing and known-case analysis. |
| Shadow mode | Mirrored live events | Evaluation team, with controlled reviewer access | None | Production-like evidence without changing the authorized decision. |
| Advisory mode | Live events | Responsible operator or reviewer | Recommendation only | Testing whether people can use the output safely and efficiently. |
| Bounded automation | Live events | Monitored workflow | Explicit low-consequence permissions | Automating a narrowly approved step after acceptance gates are met. |
Shadow mode should come before advisory or automated operation, but it does not replace offline testing. Historical replay makes rare known failures repeatable. Shadow mode reveals live data, timing, integration and workflow conditions that a fixed test set may miss.
Define the comparison before mirroring data
A useful shadow test starts with a decision statement, not an infrastructure ticket. Write down who currently decides what, which evidence is available at that moment, the required response time and the consequences of a false positive, false negative, late result or unsupported answer.
For example: “A quality engineer decides whether a surface anomaly needs secondary inspection, using the approved image, product code, station, recipe and inspection procedure within two minutes.” This is testable. “Validate the vision model on production data” is not, because it does not identify the decision or the acceptable behavior.
Next, choose the comparison target. The AI output can be compared with the contemporaneous human decision, a later confirmed outcome, an independent expert review or a deterministic rule. These are not interchangeable. A human decision shows how work was actually performed, but it may contain inconsistency or missing information. A later inspection can provide stronger evidence, but it may arrive too late for immediate scoring. An expert panel may resolve disputed cases, but only if reviewers see the evidence available at the original decision time.
NIST's March 2026 report explains that pre-deployment evaluation usually occurs in controlled environments, while real-world monitoring is needed to validate expected behavior under dynamic inputs, nondeterministic outputs and unexpected deployment consequences. [3] The shadow plan should therefore preserve both the original context and the later outcome rather than treating the first available label as unquestionable truth.
Build a one-way shadow architecture
The safest architecture mirrors evidence into an isolated evaluation path and prevents any route back to the operational system. “Read only” should be enforced by identity, network and application controls rather than a comment in code.
A practical design has six components:
- Event mirror. - Copy approved events from the historian, camera, manufacturing execution system, computerized maintenance management system or document workflow. Do not intercept or delay the production path.
- Context snapshot. - Preserve the asset or product identity, timestamp, operating mode, recipe, source quality, relevant document revision and the evidence available when the decision was made.
- Candidate runtime. - Execute the exact model, prompt, retrieval configuration, thresholds, software image and hardware profile being considered for release.
- Write-denial boundary. - Use a separate service identity with no permission to update controllers, records, work queues or notifications. Block outbound tool calls that are not required for evaluation.
- Evaluation record. - Store the candidate recommendation, uncertainty or abstention, evidence references, version, latency and any runtime error under a stable evaluation ID.
- Outcome join. - Connect the shadow record to the authorized decision and later result without rewriting the original event.
This boundary matters more in operational technology because the systems interact with the physical environment. NIST SP 800-82 emphasizes that OT security has to account for distinctive performance, reliability and safety requirements. [5] A shadow workload should not consume resources needed by the production historian, saturate an inspection network, expose a new remote-access route or create confusion about which system is authoritative.
Test the boundary itself. Attempt a prohibited write with a non-production test record and confirm that identity and network controls deny it. Stop the shadow service and confirm that the authorized workflow continues. Fill its queue, revoke its credential, delay an input and roll back its version. A design is not safely isolated until failure tests show that production remains unaffected.
Record enough evidence to reproduce each comparison
An aggregate dashboard cannot explain why a candidate passed or failed. Each shadow event needs a compact, reconstructable record.
| Record field | Why it matters |
|---|---|
| Evaluation ID and event time | Joins the candidate output to the authorized decision and later outcome. |
| Asset, product, line or document scope | Shows whether the event was inside the approved operating envelope. |
| Input references and quality state | Distinguishes model error from stale, missing or corrupted evidence. |
| Model and configuration versions | Identifies the exact candidate that produced the result. |
| Candidate recommendation and confidence or abstention | Preserves what the system would have done without pretending uncertainty is certainty. |
| Authorized decision and reason | Captures the live workflow while keeping its authority clear. |
| Confirmed outcome and confirmation time | Supports later scoring when ground truth is delayed. |
| End-to-end latency and runtime state | Shows whether a correct answer arrived in time and under healthy conditions. |
Minimize the record to what the evaluation needs. Mirroring live data does not justify copying unrestricted personal, commercial or plant information into a new store. Apply the site's retention, access, encryption and deletion controls to shadow evidence, and keep direct identifiers out when a stable pseudonymous key is sufficient.
Measure readiness across the complete workflow
There is no universal accuracy threshold that makes an industrial AI system safe to release. Acceptance criteria must follow the decision, consequence and operating envelope. NIST's Measure guidance calls for documented test sets, metrics and TEVV tools, and it says the effectiveness of the metrics and process should itself be evaluated. [1]
Use a balanced scorecard that prevents a good average from hiding an operational failure:
| Evidence dimension | Questions the shadow test should answer | Example measures |
|---|---|---|
| Coverage | Did the run include the approved lines, products, shifts, asset classes and difficult conditions? | Event count by segment, rare-condition coverage, out-of-envelope rate. |
| Decision quality | Did recommendations support the intended decision without unacceptable error? | False alarm and miss rates by consequence, calibration, expert-reviewed disagreement. |
| Abstention | Did the system stop when evidence was insufficient or outside scope? | Appropriate abstention, unsafe answer rate, reasons for abstention. |
| Timing and reliability | Did the result arrive within the decision window under real load? | End-to-end latency, timeout rate, availability, queue age and resource usage. |
| Workflow fit | Would the output reduce work without shifting hidden burden to operators? | Review time, evidence completeness, correction effort and duplicate-alert rate. |
| Traceability and safety | Can the team reconstruct the result and prove the boundary held? | Complete version records, successful outcome joins, denied writes and recovery-test results. |
Segment the results. A candidate can look strong overall while failing on night shift, one camera, a new supplier, a low-volume product or a particular asset class. Report uncertainty when sample sizes are small. Do not merge an unobserved segment into a passing average.
The August 2026 initial public draft of NIST's TEVV-Athlon Framework offers a useful structure for this work: Articulate & Organize, Define & Construct, Apply & Measure, and Synthesize & Interrogate. It frames evaluation as a customized assessment built from organizational objectives, relevant events, tools and measurement concepts. [2] Because the document remains an initial public draft, use it as current guidance rather than describing it as a final standard.
Applied to shadow mode, the stages are straightforward. State the operational objective and risk. Construct representative event groups and measurement rules. Run the candidate on live mirrored events. Then challenge the results: which segments were missing, which disagreements remain unresolved, what trade-offs appeared and what evidence would change the release decision?
Decide the run length from coverage, not the calendar
A two-week run is not automatically weaker than a two-month run, and a long run is not automatically representative. Duration matters only because it creates opportunities to observe the required conditions and outcomes.
Before starting, define coverage gates. A quality-inspection test may need every approved product family, normal lighting variation, startup and steady-state periods, known defect classes, camera cleaning, recipe change and a sample of expert-adjudicated disagreements. A maintenance test may need several asset classes, operating modes, sensor-quality states and enough completed inspections to connect recommendations with findings.
Use a minimum calendar window only where the process has real cycles, such as weekly scheduling, monthly close or a maintenance interval. Keep the run open when critical segments or delayed outcomes have not arrived. Stop early if the write-denial boundary fails, production performance is affected, evidence cannot be reconstructed or an unacceptable error pattern appears.
Treat human decisions as evidence, not perfect labels
Side-by-side agreement is useful, but agreement alone does not prove quality. The AI and operator can agree and both be wrong. They can disagree because the AI missed evidence, because the operator used undocumented context or because the task definition is ambiguous.
Create a disagreement-review process before results accumulate. Send a risk-based sample to a qualified reviewer who can inspect the original evidence, candidate output, authorized decision and later outcome without seeing irrelevant cues. Assign reason codes such as missing input, out-of-scope condition, model error, unclear procedure, timing failure, human correction or unresolved evidence.
NIST's Measure Playbook recommends input from domain experts, users and assessors who were not front-line developers, and it connects evaluation to deployment context and field data. [1] That separation reduces the risk that the team building the model also defines every disputed result in its favor.
Use explicit graduation gates
At the end of the shadow phase, do not ask whether stakeholders “feel comfortable.” Review a release packet against gates agreed before the test.
A candidate is ready to move to advisory mode only when the team can show that:
- the required operating segments and consequential edge cases were observed or explicitly remain out of scope;
- error, abstention, latency and reliability criteria were met for each important segment;
- unresolved disagreements are below the risk tolerance and do not cluster around a hidden failure mode;
- the write-denial boundary, production-isolation tests and recovery tests passed;
- evidence records can reproduce sampled decisions and connect them to later outcomes;
- responsible users can understand the output, challenge it and continue through the manual process;
- monitoring, incident ownership, rollback conditions and the next permission boundary are documented.
Promotion should add the smallest useful authority. The next stage may only show a recommendation to a quality engineer. It should not also place a hold, notify a supplier and alter a production schedule. Separate permissions make it possible to learn which part of the workflow is ready.
If a gate fails, the result is not “shadow mode failed.” It is evidence that the model, data contract, interface, operating scope or acceptance rule needs revision. Preserve the failed cases in a regression set, change one controlled element and run the affected evidence again before restarting live comparison.
A practical six-step protocol
1. Frame the decision. Name the authorized workflow, accountable owner, operating envelope, prohibited actions, decision window and failure consequences.
2. Freeze the candidate. Version the model, code, prompts, retrieval sources, thresholds, environment and data contract. Changes during the run begin a new candidate record.
3. Prove isolation. Deploy separate read-only identities, deny write paths, cap resources and test failure without disrupting production.
4. Run and join. Mirror live events, save candidate outputs and connect them to contemporaneous decisions and later outcomes with stable identifiers.
5. Review by segment. Examine coverage, errors, abstentions, timing, workflow burden, traceability and boundary tests. Adjudicate important disagreements.
6. Gate the next permission. Promote, restrict, revise or stop. If the candidate advances, enable one bounded advisory or workflow capability with monitoring and rollback already active.
Frequently asked questions
The practical takeaway
Shadow mode turns “the model worked in the demo” into a testable operational claim. It mirrors live evidence without changing the authorized process, preserves the context needed to judge each recommendation and makes promotion depend on coverage, outcomes, timing, abstention, workflow fit and safe isolation.
The strongest shadow deployment is intentionally uneventful for production. No control path changes. No record is silently updated. No operator loses authority. The change is in the quality of evidence: the team can see where the candidate helps, where it fails and exactly which permission—if any—it has earned next.