NeoBramBook a Meeting
    Machine learning and predictive AI

    Predict equipment, quality and demand problems earlier from the data your plant already produces.

    Fewer surprise stoppages, fewer off-spec batches and better plans. NeoBram uses machine learning and predictive models to combine operating data, maintenance history and equipment behaviour so your teams can prioritise where to investigate. Technical detail for evaluators is below.

    • Earlier warnings on equipment and quality
    • Better forecasts for planning
    • Measured against your own baseline
    • Reinforcement learning only where justified
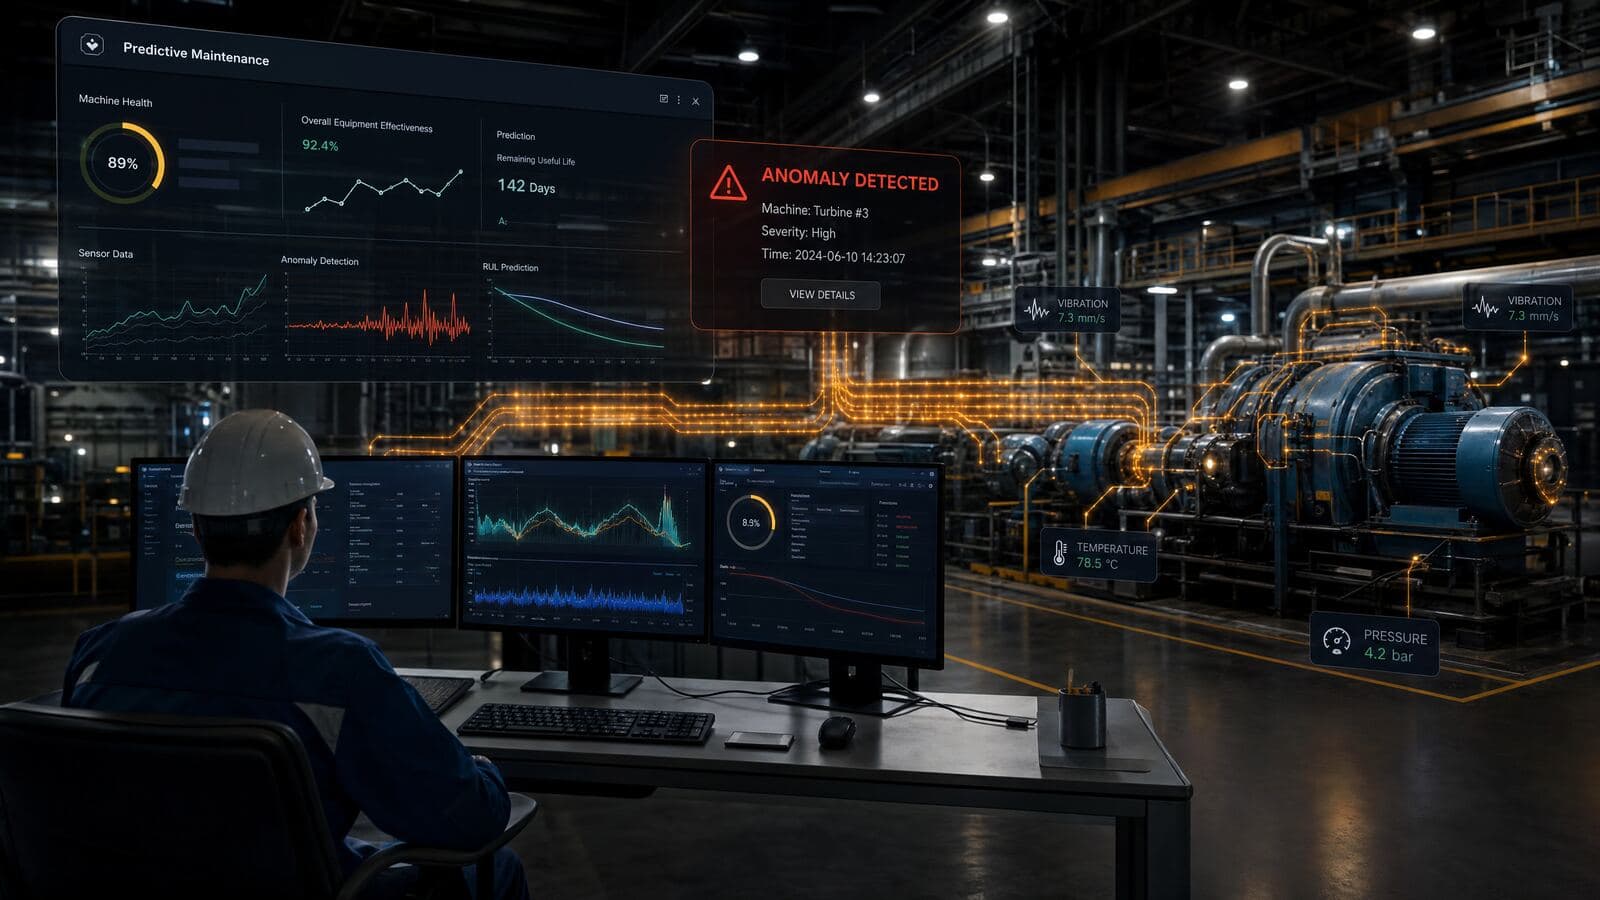
    Industrial operating data reviewed through machine learning models

    Capability first. Model and vendor selection follow the data boundary, evaluation and operating responsibility.

    Direct answer

    NeoBram helps industrial teams find equipment, quality, demand and process problems earlier and prioritise attention using machine learning on the data they already have. Behind that sit classical and advanced methods: supervised and unsupervised learning, classification, regression, anomaly and degradation detection, clustering, time-series forecasting and pattern detection, plus predictive models for maintenance, failure, quality, demand, process behaviour and operational risk. Reinforcement learning and simulation-assisted optimization are considered only where the decision is sequential and a safe learning environment exists. Every model is evaluated against a simple baseline on held-out data, and prediction accuracy is stated only with project-specific evidence.

    Industrial decision library

    Start from the decision, evidence and failure condition.

    Failure and degradation prediction

    Decision
    Which asset or component needs intervention before the next planned window?
    Minimum useful evidence
    Asset hierarchy, historian or sensor signals, operating regimes, work orders, failure history and expert-labelled events.
    Acceptance
    Useful lead time, event coverage, false-alert burden and stability by operating regime, compared with the current maintenance practice.
    Can fail when
    Failure signatures are absent from the data, labels are inconsistent, regimes change or alerts do not connect to maintenance action.

    Quality prediction and classification

    Decision
    Which batch, unit or lot is likely to fall outside specification, and which needs review?
    Minimum useful evidence
    Process parameters, material and recipe context, laboratory or inspection results and expert labels with time alignment.
    Acceptance
    Recall by defect or deviation class, false rejects, review capacity and traceability to the parameters that drove the prediction.
    Can fail when
    Post-hoc measurements leak into features, product mix changes, or a score is treated as a release decision.

    Demand, production and process forecasting

    Decision
    Which capacity, material, energy or process condition needs a planner or operator response?
    Minimum useful evidence
    Orders, actuals, calendars, constraints, setpoints, ambient conditions and known external drivers.
    Acceptance
    Error against a simple baseline by horizon and segment, bias, exception quality and planner override burden.
    Can fail when
    Structural changes are ignored, future information leaks into training, or one aggregate score hides weak products or horizons.

    Anomaly and pattern detection

    Decision
    Which combination of signals is unusual for the current operating regime and deserves expert review?
    Minimum useful evidence
    Normal-operation data across regimes, asset and unit context, event history and expert review of past anomalies.
    Acceptance
    Relevant anomalies surfaced, false alarms, investigation quality and operator acceptance.
    Can fail when
    Regime changes are reported as anomalies, tags lack context, or the model is asked to explain root cause it cannot see.

    Optimization and sequential decision support

    Decision
    Which schedule, sequence, setpoint or policy best meets the constraints the operation actually has?
    Minimum useful evidence
    A validated constraint model, actual outcomes, historical operator decisions and, for reinforcement learning, a simulator or safe bounded environment.
    Acceptance
    Constraint satisfaction, measured improvement in bounded trials, override rate and explainability to the people who must approve the change.
    Can fail when
    Constraints are incomplete, the simulator does not match reality, or reinforcement learning is applied where a rule or classical optimizer would be safer and clearer.
    Capability architecture

    Candidate components not a fixed product stack.

    Model, product and platform names may change. NeoBram selects capabilities from the intended use, representative evaluation, latency, privacy, licences, operating cost and customer support model.

    Decision framing and baseline

    Define the user, horizon, action, current method and the cost of missed and false predictions.

    Selection question: Can the proposed model beat a simple statistical or rule-based baseline in a way that changes a real decision?

    Industrial data pipeline

    Join historian, MES, ERP, CMMS, LIMS, QMS and engineering data without using information unavailable at prediction time.

    Selection question: Are timestamps, asset identifiers, units, regimes, missing data and label definitions trustworthy?

    Model family

    Choose from interpretable linear and tree-based models, gradient boosting, classical time-series methods, clustering, deep learning or reinforcement learning as the evidence supports.

    Selection question: Which model meets the evidence, latency, deployment boundary, explainability and maintenance requirement with the least unnecessary complexity?

    Evaluation harness

    Reproduce training, validation by time period, metrics by segment and comparison with the baseline.

    Selection question: Can the customer's engineers re-run the evaluation after a data, feature or model change?

    Monitoring and retraining governance

    Track input drift, performance, overrides, outcomes and model versions with approval and rollback.

    Selection question: Who owns thresholds, incidents, retraining approval and the decision to retire a model?

    Any vendor or open-source name elsewhere on the site describes an integration context. It does not imply partnership, certification or guaranteed compatibility.

    Production acceptance

    Evaluate the full workflow.

    • Compare with the current method and a simple baseline before claiming any improvement.
    • Split evaluation by time and keep future information out of training features.
    • Report performance by asset, product, regime, horizon or risk class where the decision differs.
    • Measure missed events, false alerts, lead time, calibration and human review burden, not only a headline metric.
    • Test missing, delayed, shifted, duplicate and out-of-range inputs plus safe degraded operation.
    • Monitor after process, sensor, product, recipe or operating-regime changes and regression-test before each release.

    Limitations

    Plan for failure and change.

    • NeoBram does not promise prediction accuracy without project-specific evidence from the customer's own data.
    • Historical correlation does not establish root cause or a safe intervention.
    • Rare failures and structural change can make supervised prediction unreliable; anomaly detection may be the honest starting point.
    • Reinforcement learning is not appropriate for every industrial problem and never implies autonomous control of safety-critical plant operations.
    • A better model metric does not improve operations when lead time, ownership or response capacity is weak.

    Governance sources

    Use primary guidance as a design input.

    Sources do not certify a NeoBram implementation. They help teams ask better governance, risk and architecture questions.

    AI Risk Management Framework

    U.S. National Institute of Standards and Technology

    Primary framework for governing, mapping, measuring and managing AI risk across the lifecycle.

    Direct answers

    Questions to resolve before implementation.

    Do we need deep learning?+

    Often not. Many industrial decisions are served better by interpretable tree-based or classical time-series models on well-prepared data. Deep learning earns its place for images, high-dimensional signals or language, and only when representative evidence supports it.

    When is reinforcement learning appropriate?+

    When the decision is genuinely sequential, the objective and constraints can be stated precisely, and a simulator or bounded environment allows the policy to learn without risking the plant. Scheduling, dispatch and setpoint optimization are candidates; safety-critical control is not, unless a separately validated engineering and assurance case exists.

    How much data do we need?+

    There is no universal number. Coverage of the operating regimes, outcomes and changes relevant to the decision matters more than volume. NeoBram audits event counts, context and data quality before proposing a model family or a dataset size.

    Can the models run offline or on-premises?+

    Yes. Classical and predictive models are usually light enough to run on plant servers or edge hardware, fully offline or air-gapped where required. The deployment still needs identity, logging, versioning, monitoring and a controlled update path.

    Will NeoBram guarantee an accuracy figure?+

    No. Acceptance thresholds are agreed per use case from the cost of each error, then tested on held-out data from the customer's environment. Published figures on this site are illustrative or labelled engagement statements, never guarantees.

    Use one real workflow

    Define the evidence and acceptance test before the model.

    NeoBram can lead the AI engineering while your experts retain domain, quality, safety and operating authority.

    Plan the first project